An always-on AI assistant that knows my notes, deadlines and inbox, works from every device I own, and logs every action it takes.
23,744 events
logged by daily use since Sep 2, 2026
- 39MCP tools
- 321automated tests
- 46architecture decision records
- 5clients: desktop, iPhone/iPad, terminal, Telegram, Claude Code
The problem
Siri knows nothing about my life and can't act on it. I wanted one assistant that reads my notes vault, school deadlines and email, works the same from my laptop, phone and terminal, points out what I'm forgetting — and keeps working when one AI provider hits its limit.
What I built
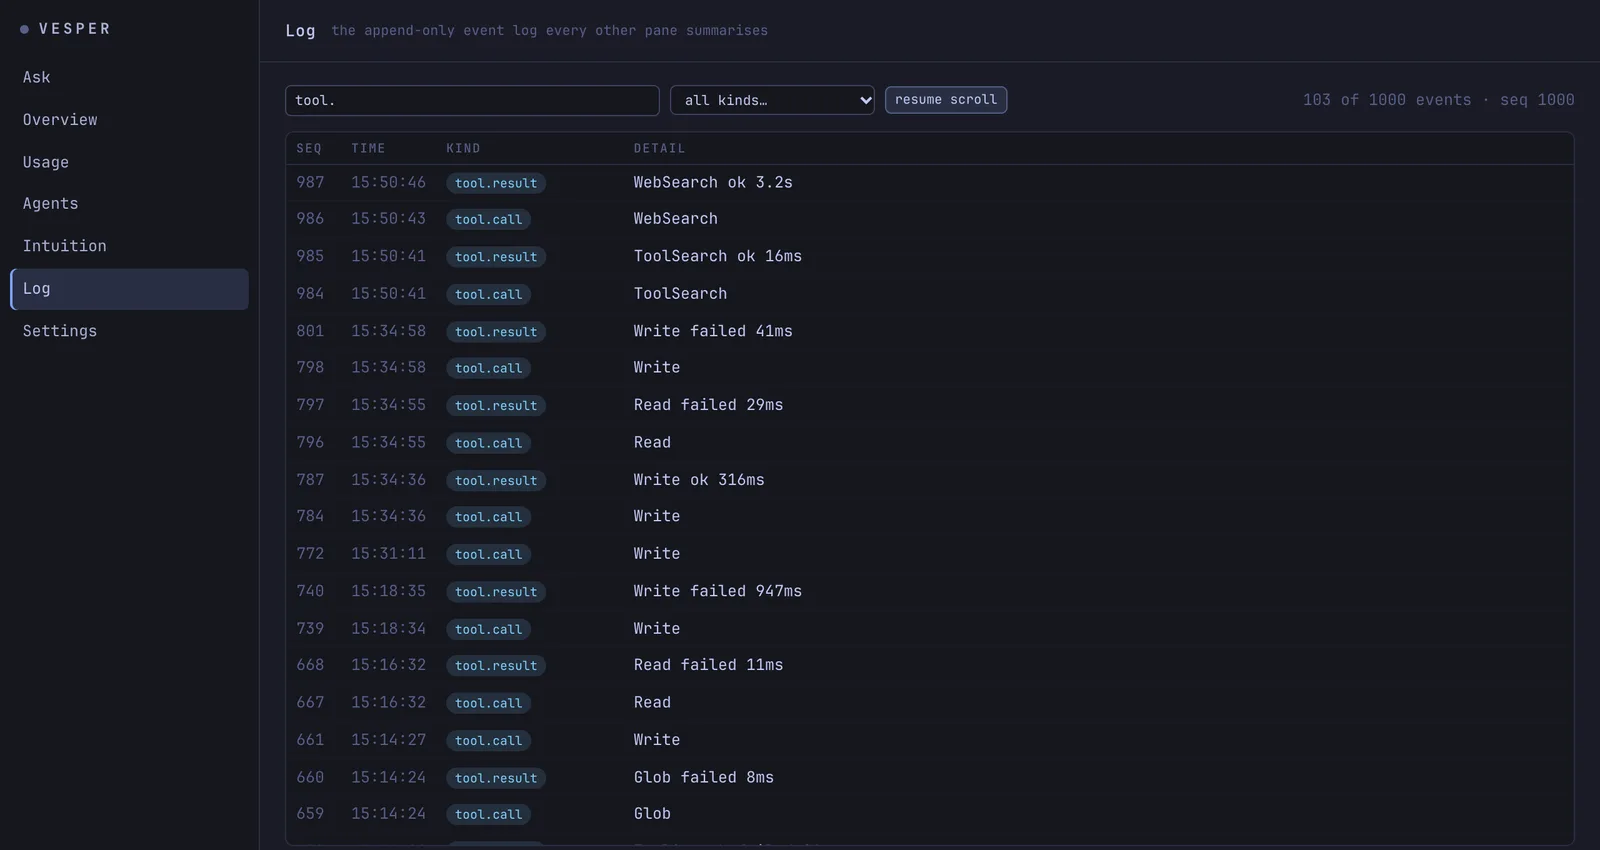
- One headless brain, thin clients. A Fastify daemon (about 80 HTTP/WebSocket routes) serves a Tauri desktop app, a terminal CLI, a native SwiftUI iPhone/iPad app with widgets and a Share extension, and a Telegram bot. Every action is written to an append-only SQLite event log before anyone is notified.
- Tools and model routing. 39 MCP tools (vault search, semantic recall, reminders, scheduling, screen vision). A router sends each request to Claude, Codex or a local Qwen model and fails over when a quota runs out — 44 of 108 routed turns were answered on-device.
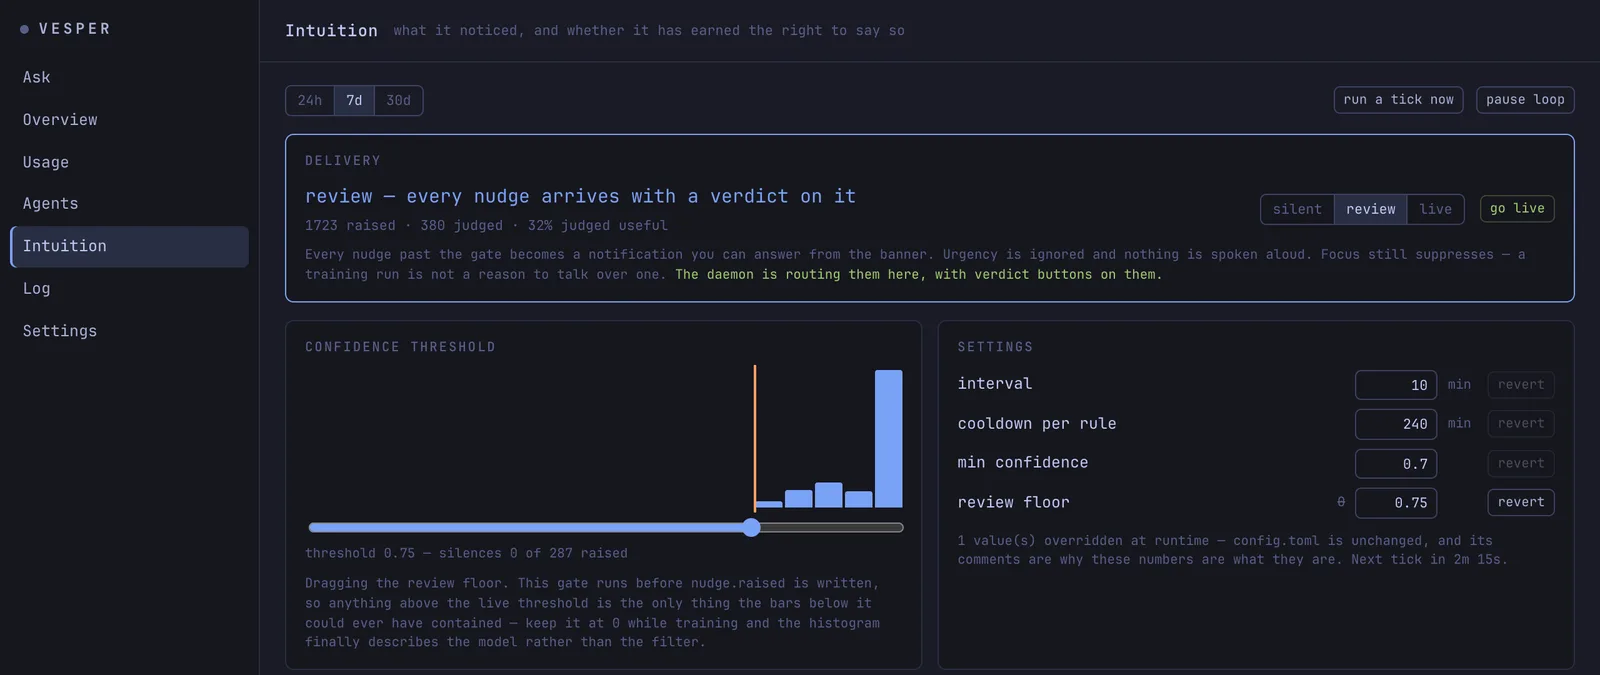
- An intuition engine that gets graded. A local model checks deadlines and the vault on every tick and raises nudges I can mark useful, wrong or noise in one tap: 1,725 nudges raised and 343 judged by hand, a dataset that drives the next fix (the nudge study).
- Local-first memory and senses. Hybrid semantic + keyword search (local embeddings, FTS5, reciprocal-rank fusion) over 5,065 chunks, fed by voice captures routed into a ~2,000-note vault that Vesper searches; on-device speech-to-text (~1.2 s for a 2.5 s clip) and screen OCR. None of it leaves the Mac.
- Built to last. 46 ADRs, 321 tests, secret scanning and dependency audits in CI. A security audit fixed 14 advisories, and a watchdog cut detection of a stuck local model from 12 days to about 75 seconds.
How it works
- Desktop · phone · terminal · Telegram
- Daemon (auth, routing)
- Claude / Codex / local Qwen
- 39 MCP tools
- Append-only event log
- Fan-out to every client
Stack
- TypeScript
- Node.js
- Fastify
- SQLite + FTS5
- MCP
- Claude Agent SDK
- Ollama (Qwen3)
- Tauri + Rust
- React
- SwiftUI
- WidgetKit
- whisper.cpp
- Python
- GitHub Actions
Proof
| Real usage | 23,744 events over 201 sessions, Sep 2 – Oct 14 2026aggregate count from the event log |
|---|---|
| Human feedback | 1,725 nudges raised · 343 judged (120 useful / 35 wrong / 188 noise)event log, Oct 15 2026 |
| Model routing | 108 routed turns: 64 to Claude, 44 to a local modelevent log |
| Engineering | 91 commits · 46 ADRs · 321 tests (211 Node, 110 Python)git history and test files |
| Reliability | stuck-model detection 12 days → ~75 sADR 0042 |
| Security | 14 advisories fixed (5 high, 1 critical); every route but /health requires a tokensecurity audit log, Oct 12 2026 |
What I'd do next
Move the brain to an always-on host and give the intuition engine a proper evaluation set built from the 343 judged nudges.
Sep 2026 – present · Private repo — it runs on my own data. Screenshots and recordings only; no code links.