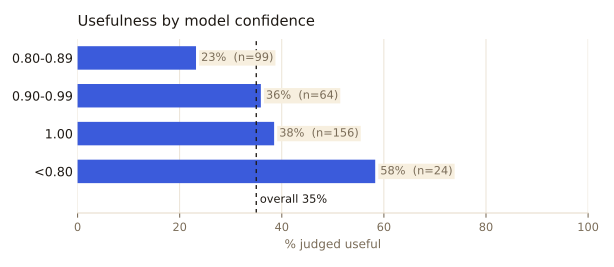
An analysis of 343 hand-judged nudges from my AI assistant that found repetition, not model confidence, separates useful from noise.
- 1,725nudges raised by Vesper's intuition engine
- 343judged by hand: useful, wrong or noise
- 0.57 → 0.69held-out AUC: model confidence alone vs. a logistic model
- −54%nudge volume under a 10-firing cap, keeping 82% of useful ones (replay)
The problem
Vesper's intuition engine checks my deadlines and inbox every ten minutes and raises nudges, and I mark each one useful, wrong or noise. Most turned out to be noise, and the obvious fix — raise the confidence threshold — assumed the model's confidence meant something. I wanted to know what actually separates a useful interruption from an annoying one before changing the engine.
What I built
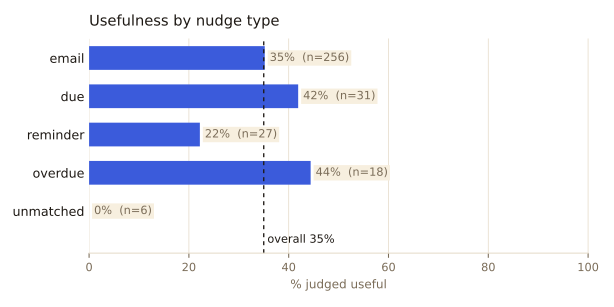
- A privacy-first export. A read-only query turns the event log into one row of features per nudge (timing, type, urgency, confidence, length, evidence count, prior firings of the same rule, verdict). No nudge text, notes or rule keys leave the database, and only aggregates are published.
- SQL breakdowns. DuckDB group-bys of usefulness by type, urgency, confidence band, time of day, week and repeat count, with any group under 5 judged nudges suppressed.
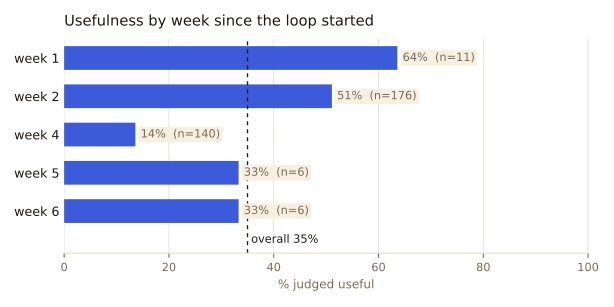
- An honest model check. A logistic regression on a time-ordered 70/30 split reaches AUC 0.69 vs. 0.57 for confidence alone, but doesn't beat a constant that already knows the test period's rate, because usefulness drifted down. That limit is reported, not hidden.
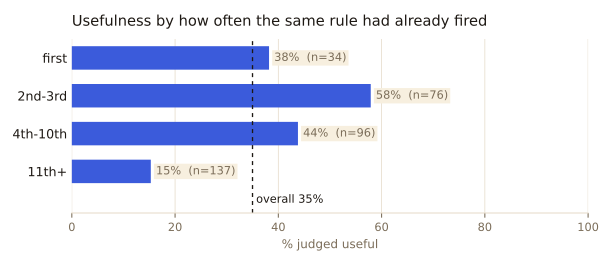
- A what-if before the fix. Replaying the judged history with a per-rule repeat cap sized the trade-off: a cap of 10 cuts volume 54%, keeps 82% of useful nudges and lifts precision from 35% to 48% — in hindsight, which is why the next step is a real before/after.
How it works
- Event log (read-only)
- Feature-only export
- DuckDB breakdowns
- Held-out logistic model
- Repeat-cap replay
- Ship the cap, re-measure
Stack
- Python
- DuckDB
- SQL
- pandas
- scikit-learn
- matplotlib
- uv
Proof
| Data | 1,725 nudges raised · 343 judged (120 useful / 35 wrong / 188 noise)Vesper event log, Sep–Oct 2026 |
|---|---|
| Repetition | 11th+ firing 15% useful (n=137) vs. 2nd–3rd 58% (n=76)findings.md |
| Model | held-out AUC 0.69 (logistic) vs. 0.57 (confidence alone); top-third precision 18% vs. 11% basetime-ordered 70/30 split |
| What-if | cap 10: volume −54%, useful kept 82%, precision 35% → 48%in-sample replay |
What I'd do next
Ship the repeat cap in Vesper, collect two weeks of new judgments, and publish the before/after precision.
Oct 2026 – present · Public repo with aggregates and charts only; the row-level export stays on my Mac, and no nudge text leaves it.