A research lab that tests AI-written trading strategies honestly, so a lucky backtest can't pass as skill.
16 of 16 lucky strategies rejected
pre-registered, graded only on data they never saw
- 518test cases
- 11point-in-time data feeds
- 21indicators, each with a no-look-ahead test
- 26MCP tools for agents
The problem
Ask an AI for a hundred trading ideas and a few will look brilliant by pure luck. Most backtesters let that through: a rule quietly reads tomorrow's prices, gets graded on the data it was tuned on, and nobody counts how many ideas were tried before the winner. alphalab is built to say no unless a strategy holds up on data it never saw, after accounting for every attempt.
What I built
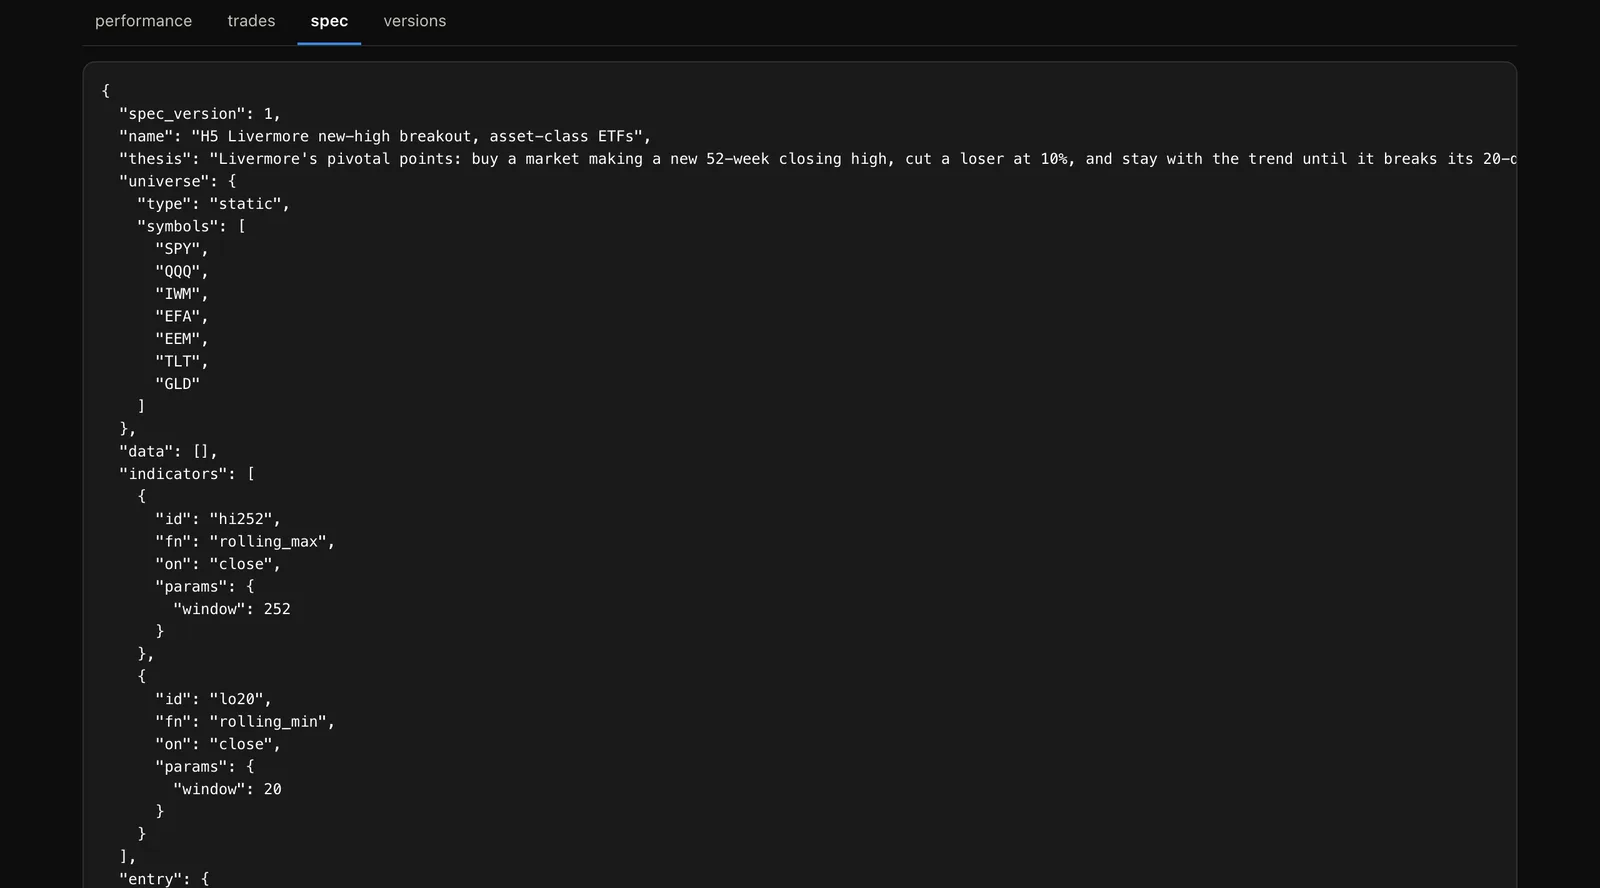
- A backtest engine that can't peek. Strategies are validated, content-hashed JSON specs, never eval'd code. A signal on day t fills at day t+1's open in exactly one place, and a structural test truncates history at several dates to prove earlier results stay bit-identical.
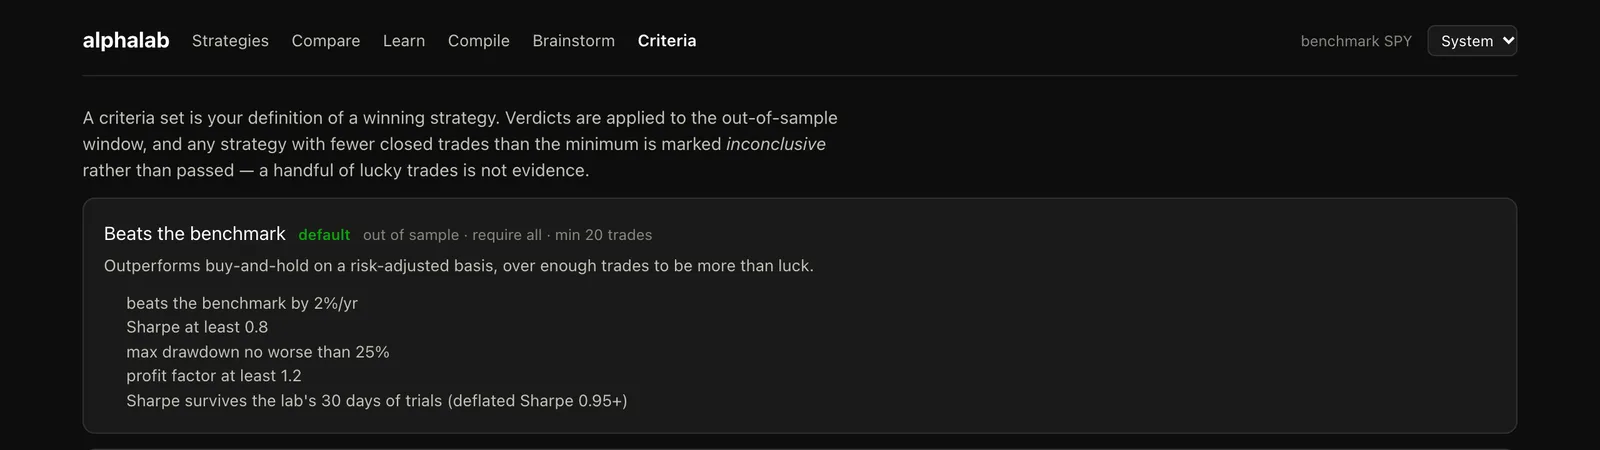
- Grading that counts every attempt. Verdicts read only out-of-sample results; fewer than 20 trades is "inconclusive", never a pass. A deflated Sharpe ratio (Bailey & López de Prado) scores each result against what the best of all recent attempts would show by luck alone.
- Point-in-time data. 11 feeds (FRED macro, SEC insider and filings, news, Reddit and more), each stamped with when it became public and joined to prices in one function, so a strategy only sees what was knowable before it trades.
- AI on top, without trusting it. Plain English compiles to a spec; a brainstorm chat can run real backtests mid-conversation; four swappable model providers; every AI output is validated before it's stored. A 26-tool MCP server lets agents use the same code paths as the CLI.
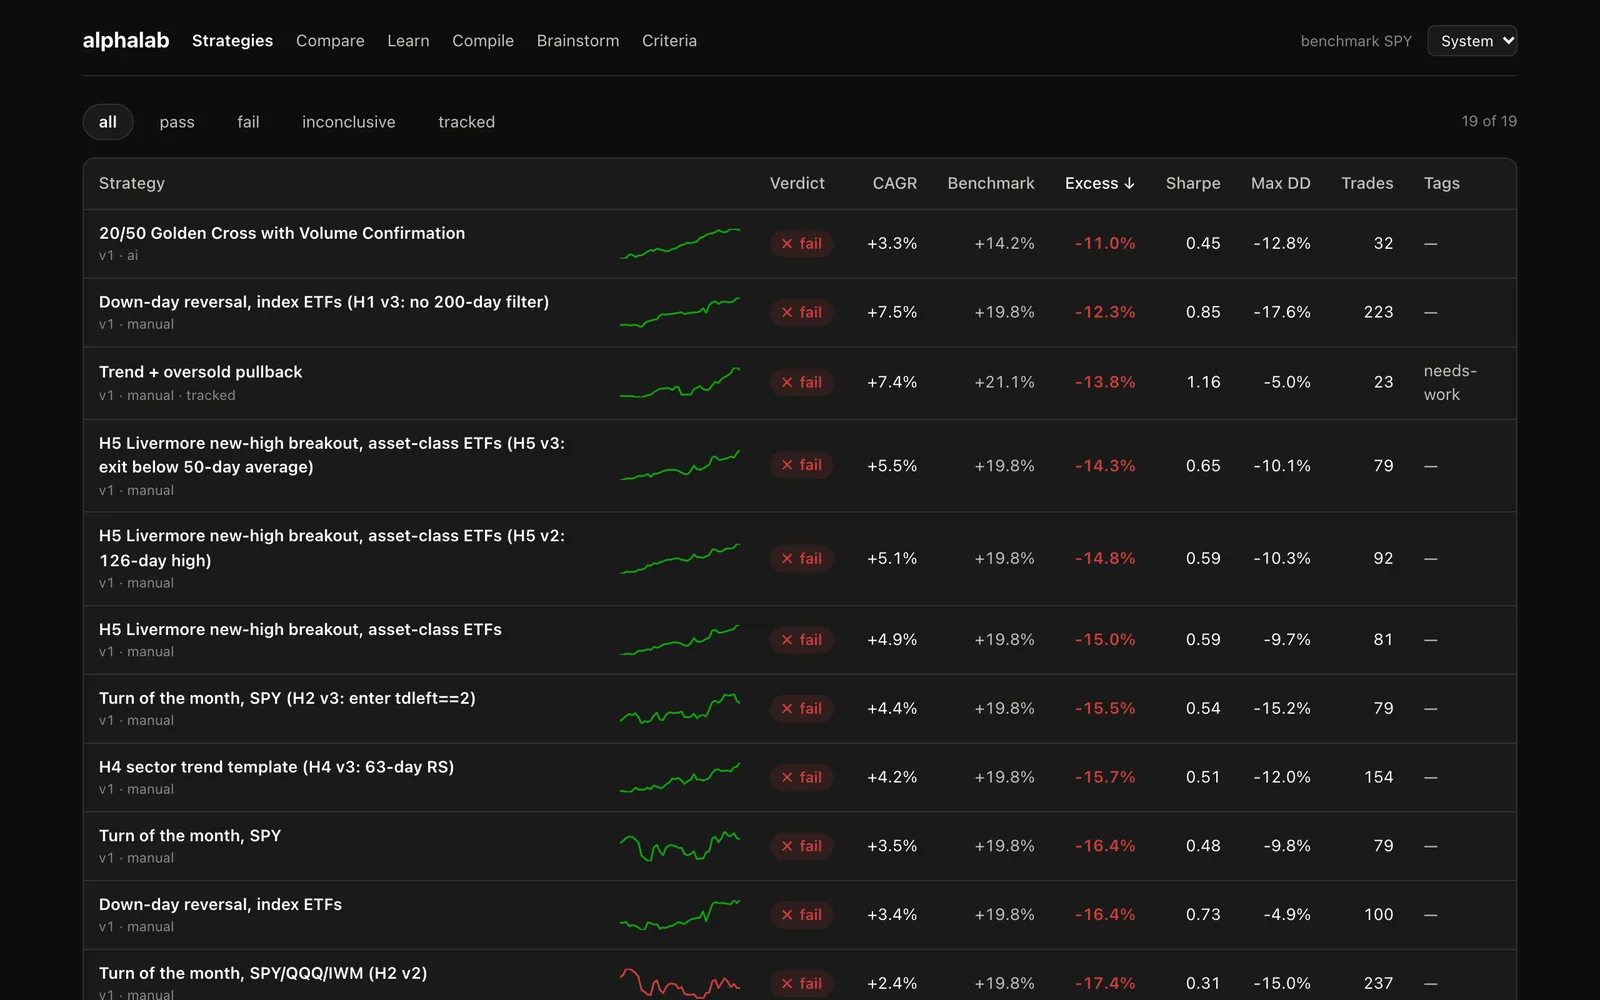
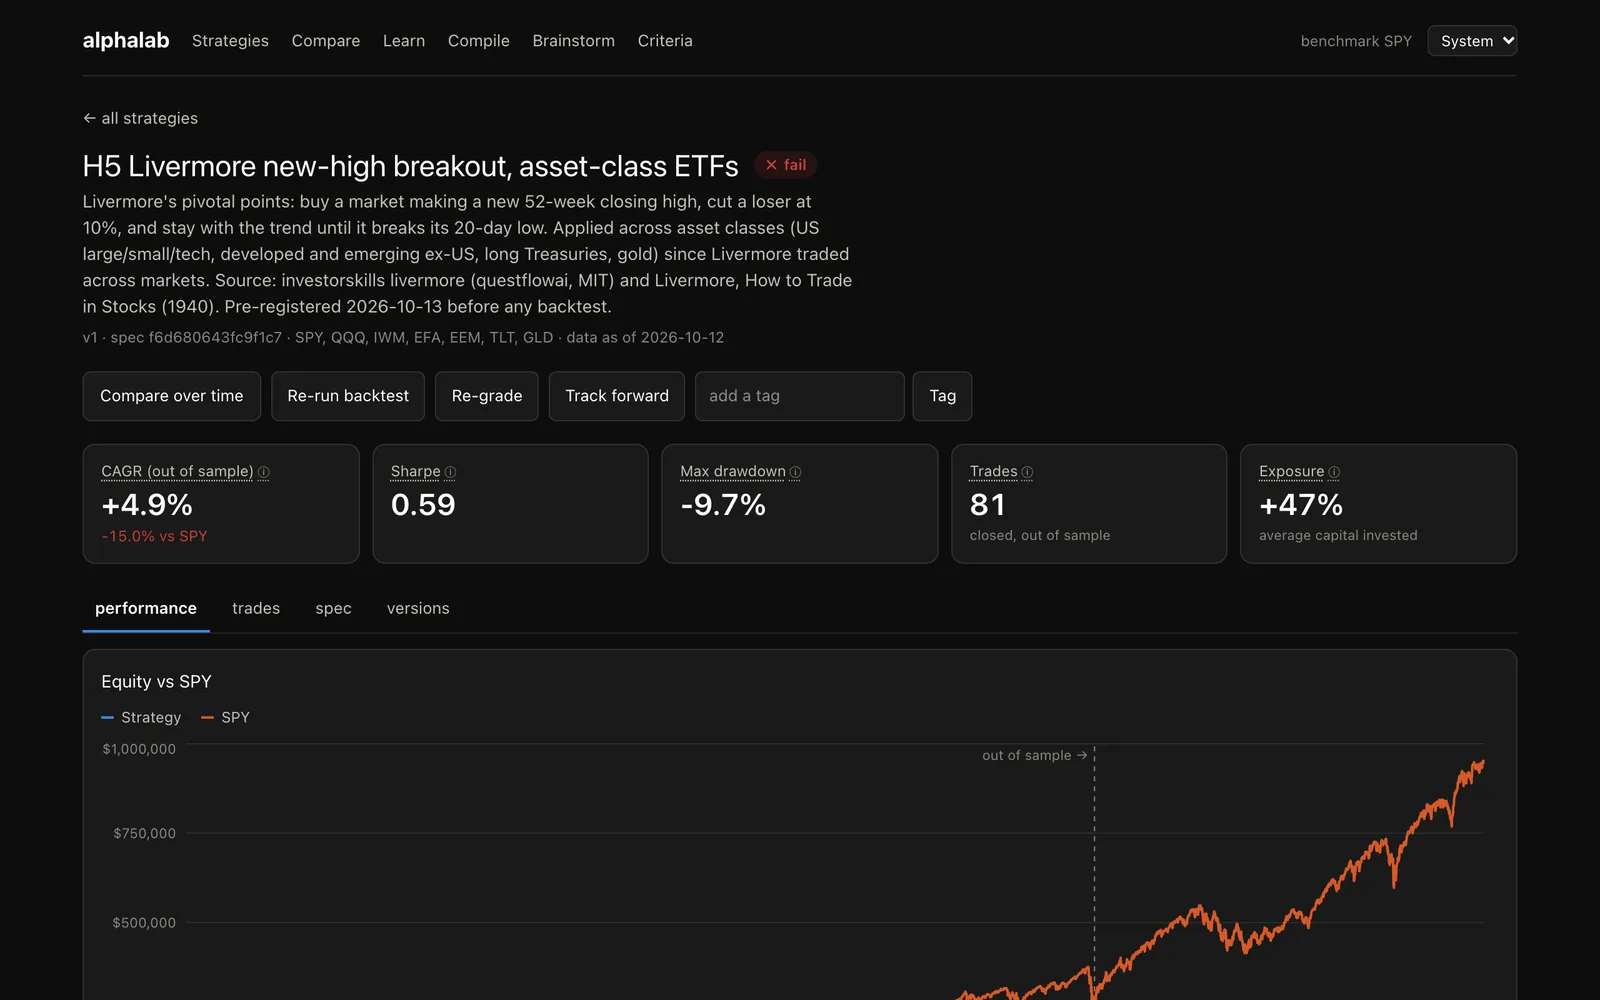
- Pre-registered research. 6 hypotheses with fixed variant budgets were written down before testing. 16 variants ran; none passed out-of-sample — exactly the outcome the lab exists to report honestly.
How it works
- Idea (English or AI)
- Validated JSON spec
- Causal backtest, t+1 fills
- Out-of-sample split
- Deflated Sharpe vs. all attempts
- Verdict: pass / fail / inconclusive
Stack
- Python 3.13
- pandas
- NumPy
- SQLite
- FastAPI
- Pydantic
- React 19
- TypeScript
- Recharts
- MCP
- Claude Agent SDK
- pytest
- GitHub Actions
Proof
| Tests | 518 collected test cases (413 functions, 30 files)pytest collection, Oct 13 2026 |
|---|---|
| Schema | v8 · 24 tables · 26 append-only triggersdatabase module |
| Research | 6 pre-registered hypotheses · 16 variants · 0 passed out-of-sampleresearch/hypotheses |
| Interfaces | 20 API endpoints · 7 dashboard pages · ~27 CLI commands · 26 MCP toolscodebase |
| Engineering | 54 commits since Sep 15 2026 · CI on every pushgit history |
What I'd do next
Let the forward-only hypothesis collect live paper results, and add an evaluation set for the English-to-spec compiler.
Sep 2026 – present · Private repo. Research method only — no returns are claimed, and no real-money or account details are shown.